SaaS & AIArchitect · Cloudpacer
CloudPacer Knowledge Base
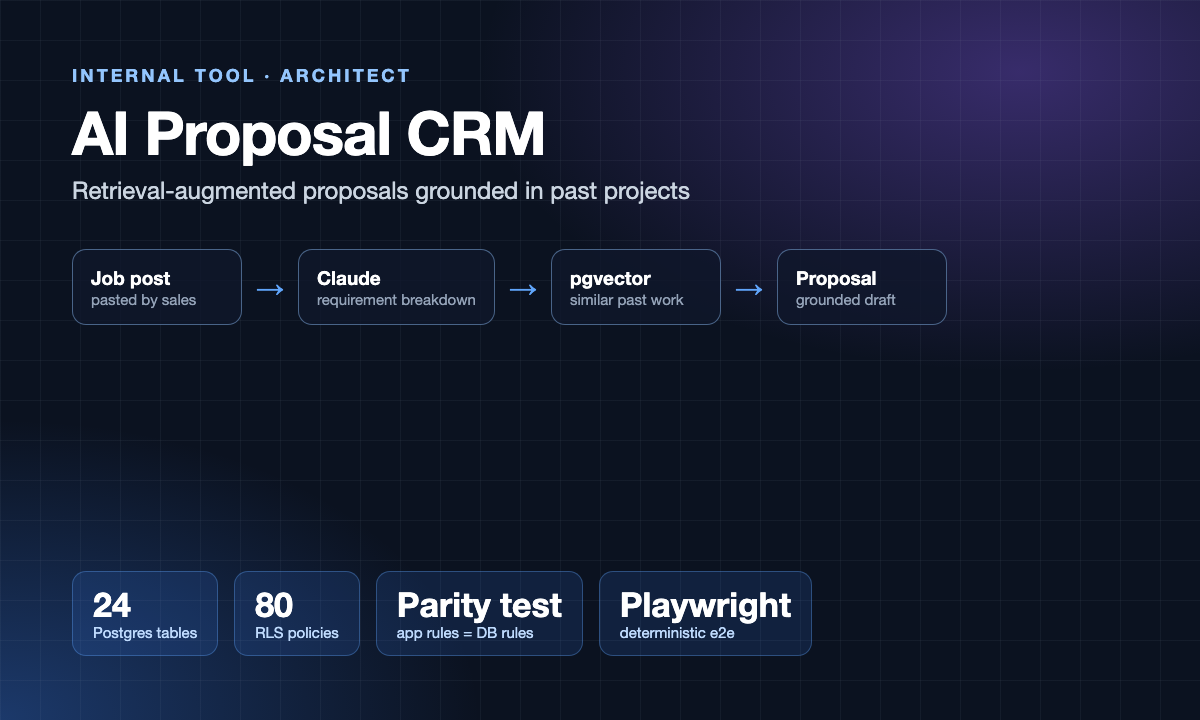
An internal knowledge base and lead CRM that finds the agency's most relevant past work for each job post and drafts a grounded proposal with Claude.
 Architected by Talha Saleem
24
tables
80+
RLS policies
4
engineers unblocked
01The problem
Cloudpacer's sales team wrote every proposal from scratch, even when the company had shipped something similar before. Knowledge of past work lived in people's heads and scattered documents.
02My contribution
Designed the system and wrote its 70-file foundation: the Supabase schema and row-level-security migrations, seed data, the can() permission engine with tests, auth and the app shell. Specified the retrieval flow (Claude breaks a job post into requirements, embeddings in pgvector find the closest past projects, the app drafts a grounded proposal), wrote the onboarding guide and a 50-ticket plan, and owned the repo, reviewing and merging the team's PRs.
- pgvector with an HNSW index for similarity search over past projects.
- Assigning a lead emails the technical owner and holds a 45-minute Google Calendar slot.
- Access is enforced twice, in the app and in Postgres, and CI fails if the two disagree.
- Found and fixed a row-level-security leak on the embeddings table.
03Outcome
Four engineers built features in parallel on that foundation. The schema has grown to 24 tables and 80+ RLS policies, and a parity test fails CI if app rules and database policies drift apart.
04Product screens
05Tech stack
- Next.js 16
- Supabase
- PostgreSQL RLS
- pgvector
- Anthropic Claude
- OpenAI Embeddings
- Google Calendar API
- Vitest
- Playwright
- Vercel
Architected by Talha Saleem
Want something like this built for you?